
Microsoft Reveals 3 Lessons From AI-Powered Vulnerability Research
Microsoft's FORGE Lab says AI-driven vulnerability discovery is reaching meaningful scale, but validation, remediation, human review and engineering capacity are becoming critical constraints.
Xcademia Team
Microsoft Says Finding Vulnerabilities Is Only Part of the AI Security Challenge
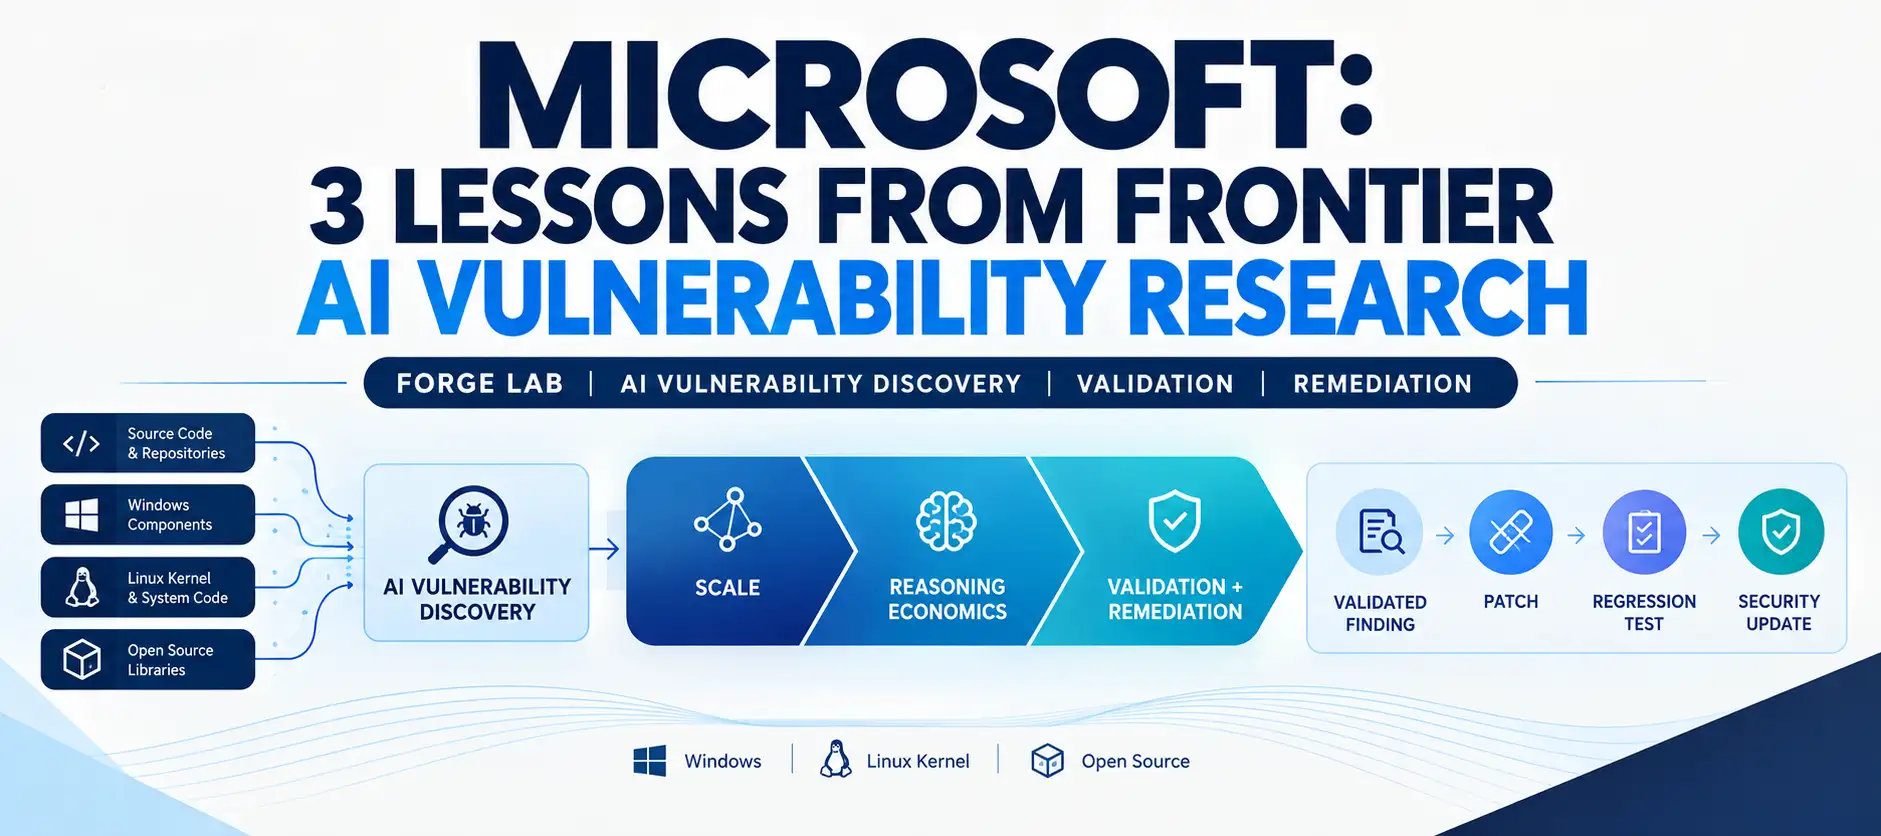
Microsoft is using its Frontier Offensive Research & Generative Exploitation, or FORGE Lab, to explore how AI-native vulnerability research can operate at scale.
The lab's mission is to advance autonomous security engineering, with a focus on finding and fixing difficult vulnerabilities.
In a new Microsoft Security Blog post, Taesoo Kim, Microsoft's Vice President of Agentic Security, outlines three lessons emerging from the lab's work across Windows, the Linux kernel and widely used open-source projects.
The lessons point to a shift in how organizations should think about AI-powered vulnerability research.
The challenge is no longer simply whether an AI system can discover a difficult vulnerability.
The larger question is whether an organization can validate, prioritize, remediate and release fixes quickly enough to keep pace with AI-assisted discovery.
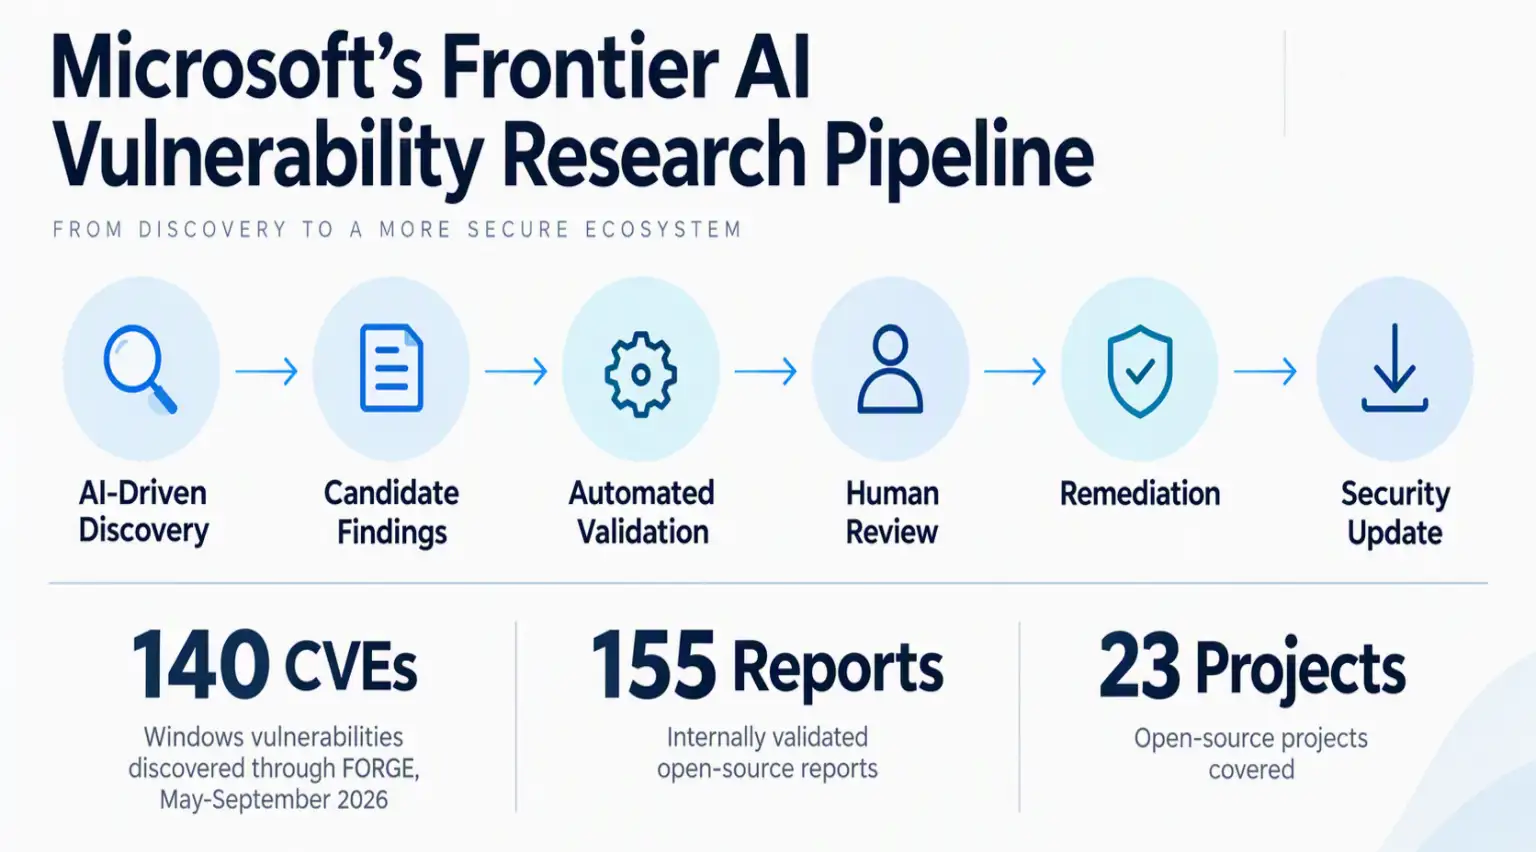
From May through September 2026, Microsoft says FORGE helped discover Windows vulnerabilities assigned 140 CVEs, including 52 addressed in Microsoft's September 2026 security release.
The work also extended beyond Windows.
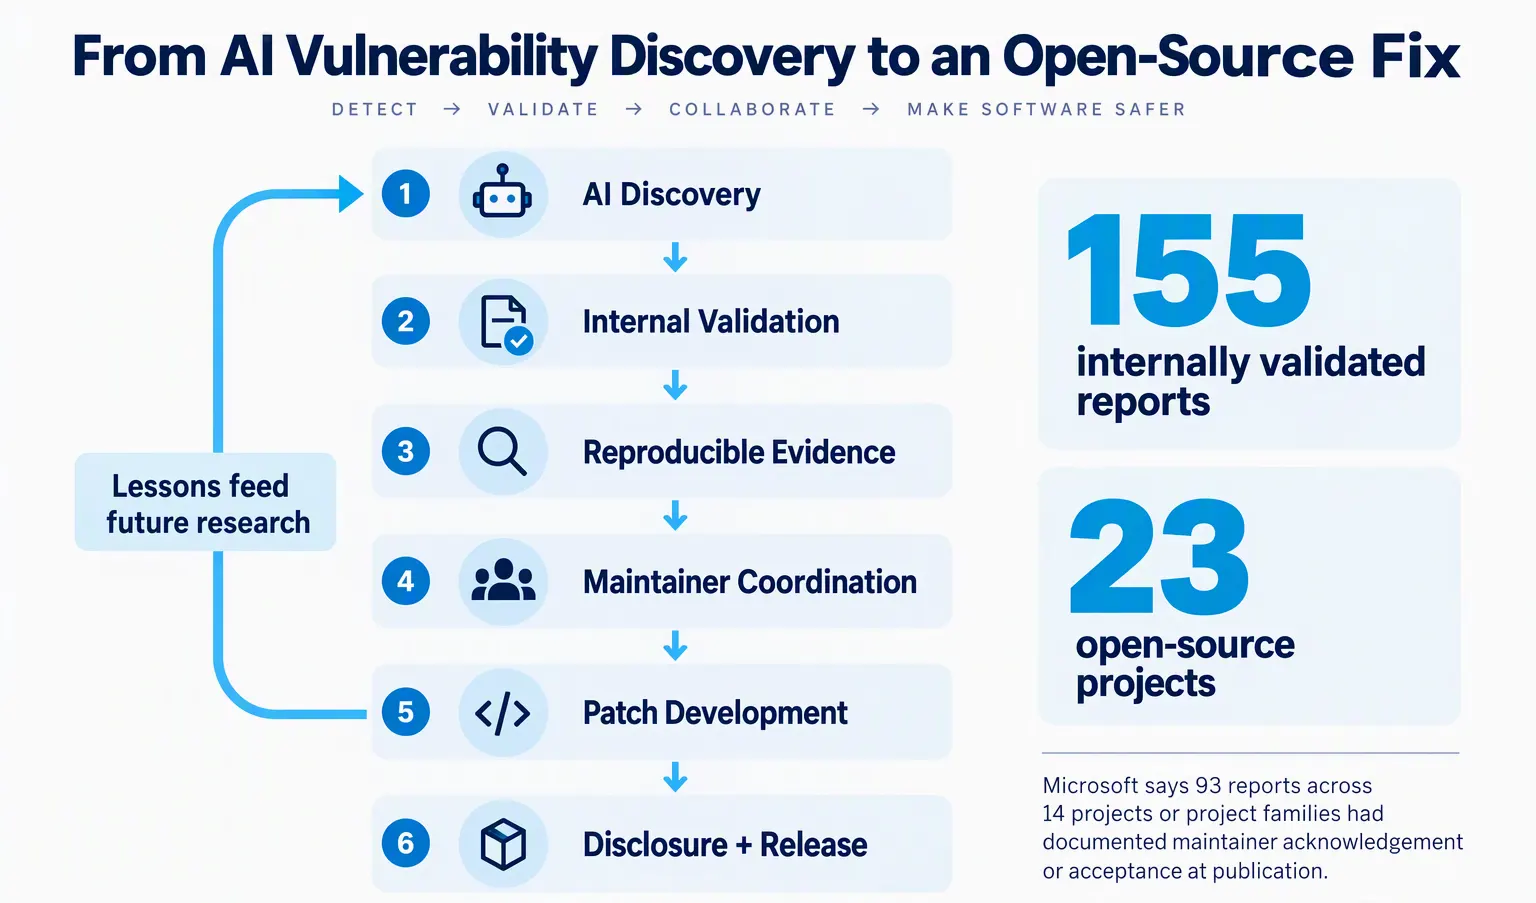
FORGE members submitted 155 internally validated reports across 23 open-source projects, including the Linux kernel.
Microsoft says 93 reports across 14 projects or project families had documented maintainer acknowledgement or acceptance at the time of publication.
One Linux kernel report also became the first Akrites submission to result in a patch merged into the Linux kernel, according to Microsoft.
Lesson 1: Frontier AI Capability Must Become Repeatable at Scale
Microsoft's first lesson is the shift from frontier capability to scale.
The frontier question is whether an AI system can find a difficult vulnerability requiring deep reasoning.
The scale question is different.
Can the system repeat that work across many targets without rebuilding the environment, investigation and review process every time?
Microsoft says better models remain important, particularly for difficult or unfamiliar vulnerability classes. But once AI-driven discovery becomes repeatable, model capability becomes only one part of the overall system.
The rest of the pipeline becomes increasingly important.
More Findings Can Create a Bigger Queue
Microsoft points out that adding more auditors or increasing the search budget can increase the number of candidate findings without necessarily increasing the number of validated vulnerabilities or shipped fixes.
If reports arrive faster than reviewers can process them, the result can be a growing queue.
Duplicate or poorly supported reports can consume attention that stronger findings need.
This changes what should be measured.
Microsoft argues that the unit worth optimizing is not simply the scan or the report.
It is a reproducible finding with enough evidence to move to the next stage.
That makes reusable preparation, deduplication and review capacity important parts of an AI vulnerability research system.
Automated Proving Can Reduce Triage Pressure
As agentic systems produce more candidates, Microsoft says the bottleneck shifts toward determining which findings are real, reachable and security-relevant.
Project-specific automated provers can help bridge this gap.
These include:
Proof of vulnerability or proof-of-concept generators
Harness builders
Trigger-input finders
Tools for confirming reachable execution paths
Regression-ready trigger generation
Microsoft says these tools can help establish reproducible evidence within a project's build and test environment.
The company also reports that one internal project using deterministic algorithms such as abstract syntax trees, or ASTs, reduced about 45% of duplicate findings across multiple scans of the same code.
According to Microsoft, reducing duplicates also reduced the load on its proof-of-concept generator and subsequent human triage.
The broader lesson is that increasing candidate volume does not automatically increase useful security output.
More findings do not create more throughput when the review queue grows faster than fixes ship.
Lesson 2: Optimize Reasoning Economics, Not Just Token Consumption
The second lesson moves from token consumption to reasoning economics.
At scale, repeated orientation, speculative reasoning and redundant analysis all consume resources.
But Microsoft argues that minimizing token usage alone is not the right objective.
A short report can be inexpensive to generate but expensive to investigate if it does not answer the important technical question.
A longer analysis may be more valuable if it establishes the missing execution path or provides evidence needed to make a decision.
The important question is therefore:
Where will the next unit of reasoning change the decision?
AI Should Focus on the Remaining Evidence Gap
Microsoft provides several examples.
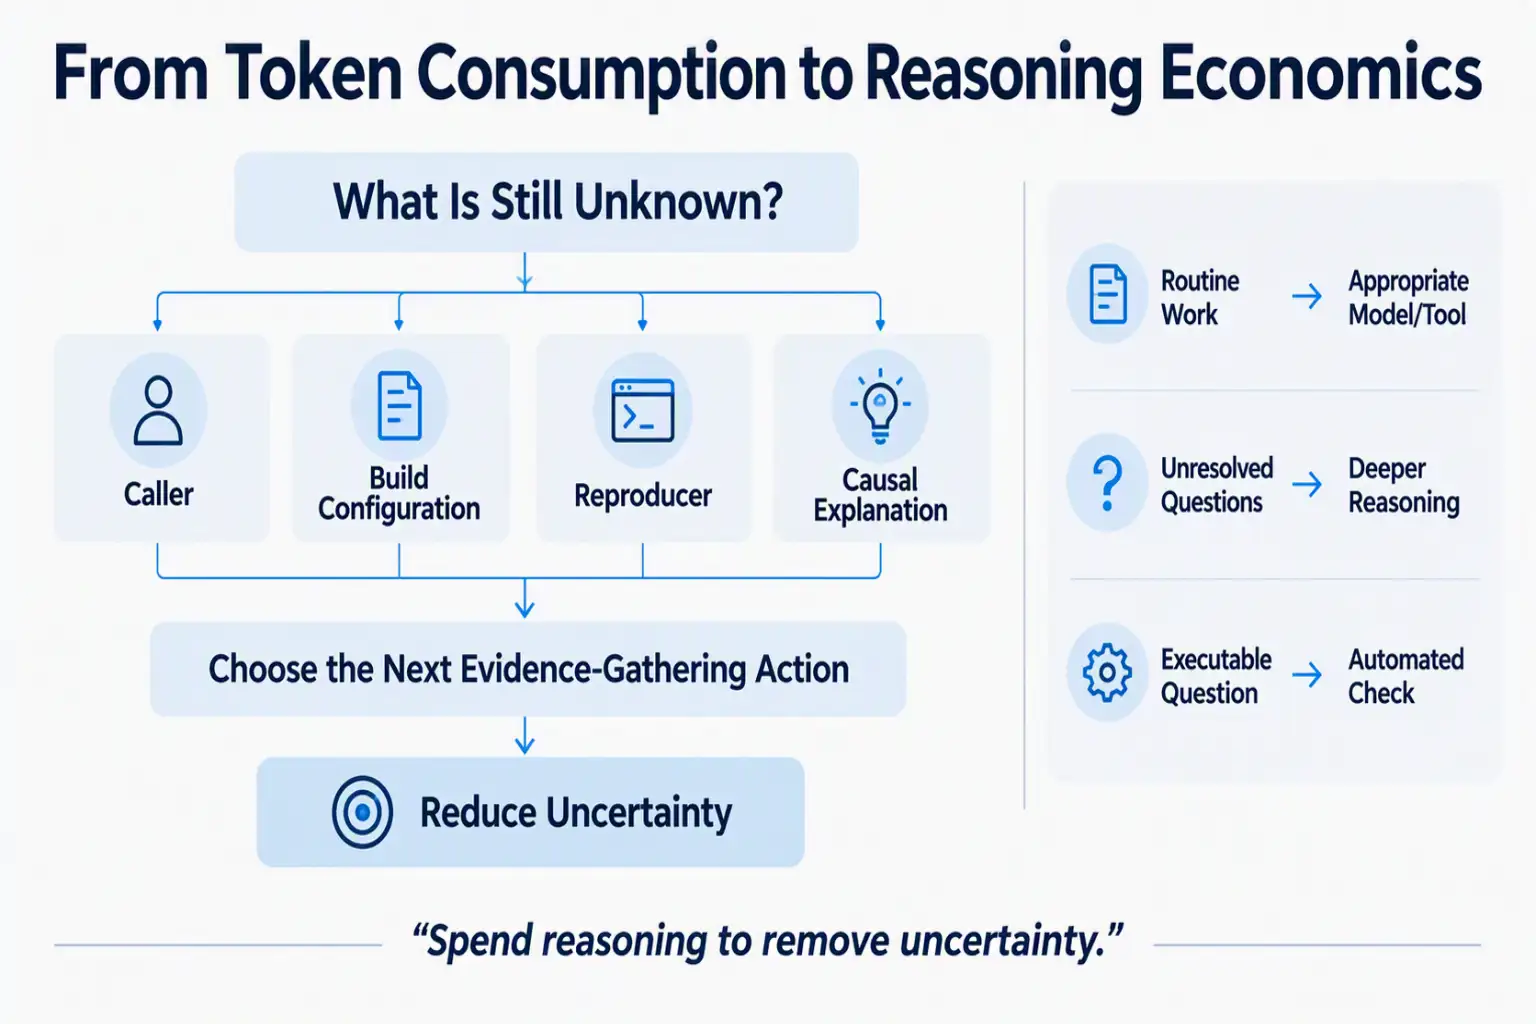
If an index can already identify callers, asking a frontier model to rediscover them may waste reasoning capacity.
If the uncertainty concerns whether two lifetime conditions can coexist across callbacks, deeper reasoning may be appropriate.
If the question is whether an input triggers a failure, an executable check may provide stronger evidence than additional prose.
This leads to a more targeted approach to AI resource allocation.
The system should first identify what remains unknown.
That could be:
A caller
A build configuration
A reproducer
A causal explanation
The next action should then address that specific uncertainty.
Repeating an analysis without adding evidence can consume more resources without reducing uncertainty.
MDASH Combines Different Models and Tools
Microsoft says FORGE uses a multi-model agentic scanning harness called MDASH.
The system combines:
Frontier models
Distilled models
Specialized auditors
Code-analysis tools
The purpose is to allocate different tasks to different capabilities.
Microsoft cautions that this does not automatically guarantee optimal allocation.
Routing routine tasks to cheaper models, reusing verified context and escalating unresolved questions to stronger reasoning are approaches that still need to be tested and measured.
The company therefore frames reasoning allocation as an engineering problem rather than an assumed efficiency gain.
Vulnerability Scanning Can Become a Learning Loop
Microsoft's second lesson also extends beyond individual investigations.
The company argues that vulnerability scanning at scale should become a training loop, not only a discovery pipeline.
Each MDASH run can produce signals such as:
True-positive and false-positive decisions
Duplicate findings
Failed reachability claims
Reviewer feedback
Verification results
Severity assessments
Patch outcomes
Regression-test evidence
Microsoft says capturing these signals alongside the relevant code context and causal reasoning can create datasets for reinforcement learning and fine-tuning specialized cybersecurity models.
The goal is not simply to teach future models what vulnerabilities look like.
It is also to help models learn which findings survive validation, which explanations help humans and automated provers act, and which patterns lead to useful remediation.
Microsoft's principle is clear: spend reasoning to remove uncertainty, not simply to produce more analysis.
Lesson 3: Validation and Remediation Must Become a Continuous Loop
The third lesson is the shift from isolated discovery to coordinated validation and remediation.
Microsoft argues that validation and remediation should not be treated as downstream cleanup after vulnerability discovery.
They are part of the discovery loop itself.
Each candidate should move through a process that can include:
Automated verification → Human review → Patch development → Regression testing
Each stage should return evidence to the system.
A reproducible trigger can strengthen the original finding, guide the fix and become the foundation for a regression test.
A failed validation can also provide useful information if the system records why the candidate failed.
Microsoft lists examples such as:
An unreachable path
A missing precondition
Incorrect build configuration
Insufficient attacker control
A duplicate report
An incomplete causal explanation
The objective is to make every investigation leave reusable knowledge behind.
That could mean a validated trigger, clearer invariant, stronger harness, improved regression test or routing rule that prevents the same mistake in future investigations.
Connecting Discovery to the Engineering Loop
Microsoft says a reproducible defect is not yet a serviced fix.
To shorten the path from discovery to remediation, MDASH needs to operate as part of the engineering process.
That means connecting vulnerability research with:
Code
Builds
Artifacts
CI/CD environments
Validation results
Development workflows
Servicing processes
Broad analysis can identify suspicious code paths.
But reproducing a candidate defect may require the correct binaries, symbols, configurations, harnesses and runtime conditions.
Each stage therefore needs a clear owner and machine-usable evidence.
Microsoft describes the handoff as follows:
Research provides the candidate claim, causal path and uncertainty.
Proving provides execution evidence from the relevant build artifact.
Component teams assess the violated invariant, repair strategy, compatibility risk and related variants.
Servicing connects the approved change to release validation.
Importantly, Microsoft says failed reproductions, rejected findings, incomplete patches and regression results should return to MDASH as structured evidence rather than simply becoming another item in a separate queue.
The goal is not to remove human code review or release validation.
Instead, Microsoft wants to automate repeatable work around those activities while preserving engineering accountability.
FORGE Extends Beyond Windows Into Open Source
Microsoft's FORGE work also covers open-source software.
The company says its researchers submitted 155 internally validated reports across 23 open-source projects spanning areas including kernels, runtimes, networking libraries, container technologies and media parsers.
At the time of publication, 93 reports across 14 projects or project families had documented maintainer acknowledgement or acceptance.
The projects listed by Microsoft include:
apple/container
apple/containerization
curl
Escargot
FFmpeg
Hyperlight
Linux
llama.cpp
Node.js
PyRIT
Rust
SQLite
vLLM
Microsoft notes that these reports were at different stages of the disclosure process, so only subsets were publicly disclosed at the time of publication.
The company's public examples include vulnerabilities affecting curl, Node.js and the Linux kernel.
Open-Source Security Requires More Than Larger Scans
Microsoft says open-source vulnerability research presents its own operational challenges.
Each project has different:
Build environments
Analysis requirements
Maintainer workflows
Review capacity
Disclosure preferences
Technical contexts
Some projects may require a patch while others may not.
Some prefer private disclosure while others use public channels.
Maintainers can also differ in how they interpret whether an issue crosses a security boundary.
Microsoft says scaling AI-assisted vulnerability discovery therefore requires research teams to absorb this complexity rather than simply passing a larger volume of findings to maintainers.
The broader lesson is that a larger AI scan is not enough.
The surrounding process for reproduction, disclosure, remediation and communication must scale as well.
Measuring the Cost of Automated Validation
Microsoft also provides measurements from automated validation work involving the Linux kernel.
According to the company, MDASH surfaced thousands of suspicious locations in the Linux kernel.
Its validation agents produced supporting evidence for 627 findings.
For a subset of this work, Microsoft reports:
182 confirmed crash findings had an average proof-of-concept generation cost of $3.61 in model cost and 21.5 minutes.
Six selected cases tested for local privilege-escalation potential using automatic exploit generation averaged $8.56 and 25.4 minutes.
Microsoft says these evaluations used GPT-5.5 without extensive task-specific tuning of the model or harness.
Important Scope of the Cost Figures
Microsoft explicitly says these averages include all attempts associated with the successful cases shown.
They exclude:
Initial screening
Candidates that failed
Candidates filtered out
Human investigation
Patch preparation
Therefore, the figures should not be interpreted as the total cost of an end-to-end vulnerability discovery and remediation process.
Microsoft says the results nevertheless indicate that automated validation can produce useful results at what it describes as practical cost and latency, including at Linux kernel scale.
The company also suggests that tighter co-design between models and agent harnesses could improve validation yield and efficiency.
Microsoft says that if validation costs were reduced by another order of magnitude, the range of findings that could be economically validated could expand substantially.
That is presented as a potential implication, not a measured outcome from the current study.
FORGE OSS Bug Hunt Party Tests Human Coordination at Scale
Technical validation is only one part of open-source vulnerability research.
Microsoft says its experience also showed the importance of understanding each project's workflow and working directly with maintainers.
To expand this human coordination, Microsoft hosted the FORGE Open Source Software Bug Hunt Party, also referred to as Project Sunshine, during its annual Hackathon.
The initiative gave developers across Microsoft an opportunity to exchange security research practices and gain hands-on experience with vulnerability investigation, validation and responsible reporting.
Microsoft says 50 participants produced 39 reports across six projects.
The projects included:
Microsoft Hyperlight
Linux
vLLM
Gemini CLI
llama.cpp
Microsoft says these 39 reports are included in the broader 155-report snapshot.
The company also says Project Sunshine has continued beyond the Hackathon as a forum for open-source security collaboration within Microsoft.
Akrites Connects Research With Coordinated Remediation
Microsoft is also contributing to Akrites, a Linux Foundation initiative focused on confidential remediation and disclosure for vulnerabilities in critical open-source software.
FORGE submitted nine Linux findings with internally assessed CVSS scores above 7.0.
Microsoft says that, together with submissions from other participants including Google, these cases helped test and refine Akrites' early Coordinated Vulnerability Disclosure workflow.
One of the FORGE reports became the first Akrites submission to result in a patch merged into the Linux kernel.
Microsoft says FORGE plans to continue contributing to responsible disclosure efforts.
The work illustrates the difference between finding a vulnerability and moving it through the full remediation process.
A successful security workflow requires reproducible evidence, a causal explanation, severity assessment and an understanding of potentially affected downstream projects.
What Microsoft's FORGE Lab Is Measuring Next
Microsoft says FORGE's next phase will focus on measuring the complete vulnerability research pipeline rather than simply counting findings.
The company identifies several measures that matter:
Candidate arrivals
Duplicate findings
Rejected reports
Validated defects
Queue age
Unresolved cases
Time spent at each stage
Microsoft also says reasoning economics should be evaluated through both model cost and human review time.
The question is not simply how many tokens an AI system consumes.
It is whether additional reasoning:
Removes uncertainty
Improves coverage
Produces independently validated findings
The third area is continuous validation and remediation.
Microsoft says future evaluation should include:
Reproduction success
Patch rework
Regression evidence
Time from validated defect to approved fix and release
For security leaders evaluating AI-powered vulnerability discovery, Microsoft's recommendation is to measure validated fixes rather than findings alone, while also considering model cost and human review effort.
The Bigger Picture: AI Vulnerability Research Is Becoming a Systems Problem
Microsoft's FORGE research points to a broader shift in AI-powered cybersecurity.
The difficult question is increasingly not whether an AI system can find a vulnerability.
It is whether the organization around that system can process the resulting findings without overwhelming human reviewers, engineering teams and maintainers.
The three lessons are closely connected.
Frontier capability must become scalable.
Reasoning must be allocated where it removes meaningful uncertainty.
Discovery must connect continuously to validation and remediation.
Microsoft's results show the scale it is already testing: 140 Windows CVEs from May through September 2026, 155 internally validated open-source reports across 23 projects, and automated validation measurements from Linux kernel research.
But the company also emphasizes the constraints behind those numbers.
More findings do not necessarily mean more security if validation queues grow faster than fixes can ship.
More model reasoning does not necessarily mean better outcomes if it does not close an evidence gap.
And a reproducible vulnerability does not become a security improvement until the organization can validate, fix, test and release the appropriate remediation.
For security leaders, that makes the surrounding system as important as the model itself.
The next phase of AI-native vulnerability research may therefore be measured less by how many vulnerabilities an agent can discover and more by how reliably an organization can turn credible discoveries into validated and released fixes.
Source: Microsoft Security Blog
About the Author